AI-Powered. Evidence-Based.
Discover how Large Language Models are transforming one of offensive security's most labor-intensive processes: vulnerability research and patch diffing.
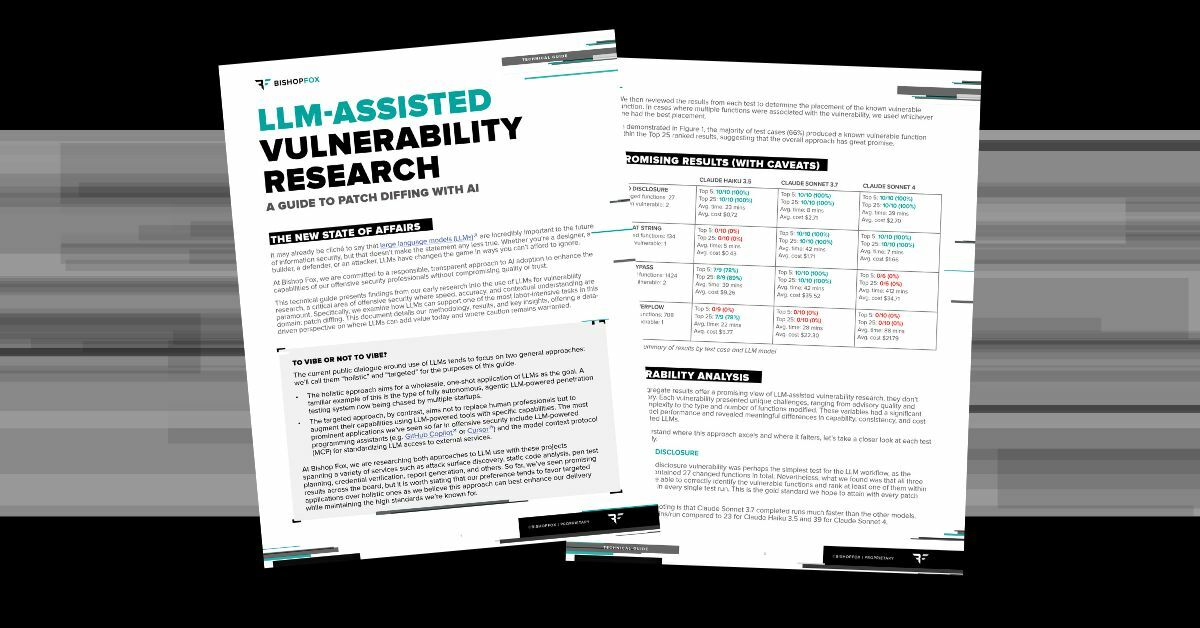
This technical guide documents Bishop Fox's experimental research into AI applications for security analysis. Authored by Jon Williams, it presents our approach to testing three Claude models against four high-impact CVEs across different vulnerability classes.
Inside This Guide:
- Experimental Methodology: Testing approach across vulnerabilities within the following classes: information disclosure, format string injection, authorization bypass, and stack buffer overflow
- Performance Analysis: Results including success rates, cost analysis, and time measurements across different LLM models
- Technical Implementation: Binary decompilation workflow, differential report generation, and structured prompting techniques using our raink tool
- Key Insights: Where LLMs excelled, where they struggled, and practical implications for security teams
Whether you're evaluating AI integration or conducting LLM research, this guide provides experimental findings to inform your exploration.